 komrad
Data flow
How komrad efficiently renders the UI and reacts to writes in Postgres
Komrad keeps one source of truth for state, and moves data in one direction.
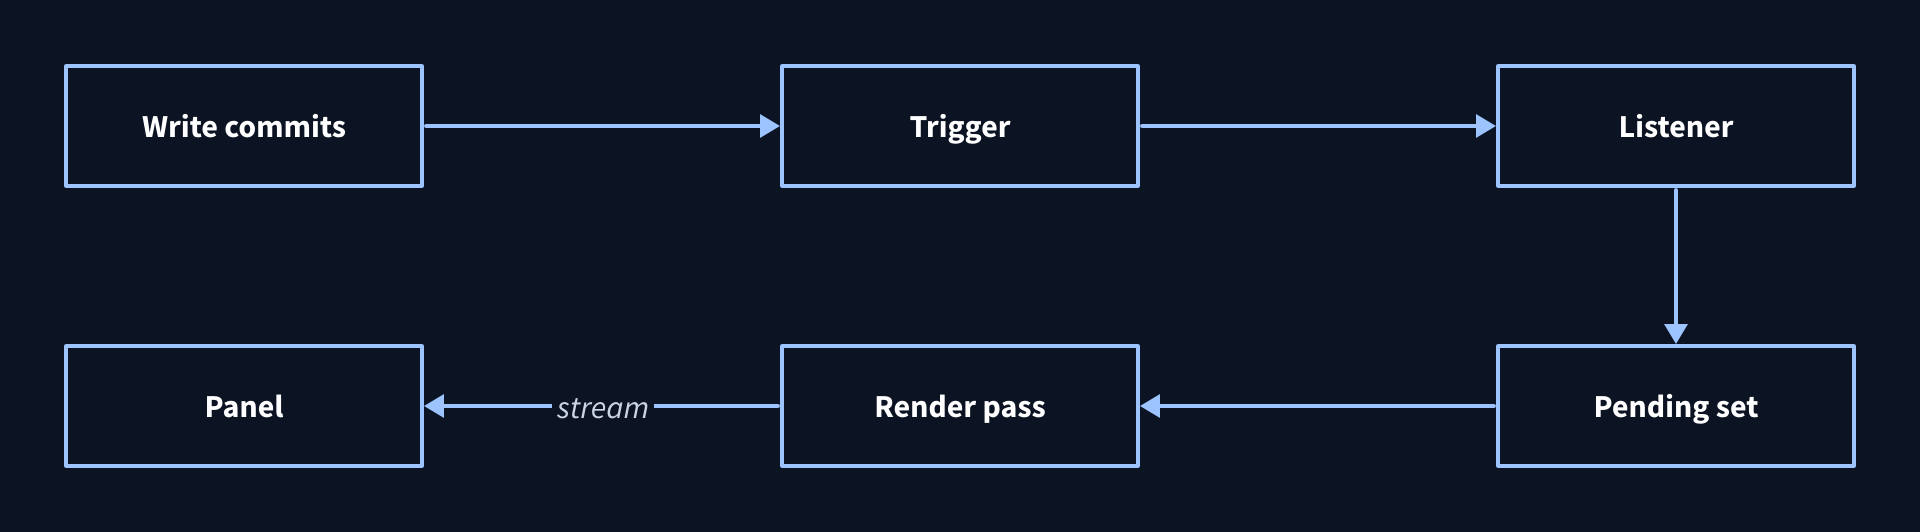
All API (or CLI, or MCP) calls write data to Postgres. Those writes trigger notifications back to the server, which re-reads the changed data, and streams it to every panel.
The server never polls the database, and neither the panel nor the server holds state the database doesn’t have.
Two well-known patterns cover most of it. The notifications follow the event notification pattern, where an event says only that something changed and the reader fetches the current state itself. The loops are level-triggered, like Kubernetes controllers.
Triggers#
Every table the panel draws has a trigger. When a row is inserted, updated or deleted, the trigger calls pg_notify with the table name and the row’s key and nothing else, which tells the server which row to look at. The trigger runs inside the transaction, so the notification goes out only if the write commits.
The listener and streaming#
Once the event is received, the server adds that notification key to a pending set, and pokes the render loop. This poke goes through a Go channel, to handle backpressure. If the poke is dropped, it’s no big deal — Komrad will simply re-read the full UI state again. This is a simpler model then attempting to replay events, and is effective for a tool of Komrad’s size.
The render loop reads the pending rows back with the same queries the List RPCs use. Each subscriber remembers what it was last sent and gets only what differs. Rows that no longer exists are tombstoned.
It’s important to understand that notifications only hint that something changed, and komrad doesn’t store notifications or replay them. If the listener’s connection drops, the server drops every subscriber too, and each one reconnects and takes a fresh snapshot. A subscriber that falls too far behind is dropped the same way. This means that lost notifications cost one re-read, and the screen will still end up being accurate.
Sync loops#
Not all state is controlled via Komrad. In some cases, komrad is syncing in external state, like Github PR comments or CI/CD data. For these, the server runs reconciliation loops that check on a timer and write what they find to Postgres. When they do, they trigger the same notification stream to the server.
The reconcile loop is also relevant for agent state. Komrad, for instance, reads the bottom of each agent’s pane and decides whether the agent is working, waiting or idle. Other loops deliver mail, sync pull requests, and measure worktrees.
Waking a loop#
Some changes should show up faster than a loop’s timer allows. When you merge a pull request, you expect to see it right away. Komrad still won’t patch state directly to get there! This would violate the single-data-flow principle. Instead, the server wakes the loop for that resource.
The wake doesn’t provide the data, it only tells the loop to look again. Rebases work like this, for instance: they wake the loop that reads each checkout’s branch and head.
Jobs#
One last area to consider: some work needs to happen on a schedule.
This work is handled through River, a job queue that lives in the same Postgres. Launching an agent for a schedule is a River job, and so is deleting an agent. The delete claims the row in the same step that queues the job, so pressing the key twice can’t queue the work twice.
Each kind of job has a queue of its own.